Loading...
Searching...
No Matches
Mila::Dnn::CausalConv1d< TDeviceType, TPrecision > Class Template Referenceexport
module Dnn.Components.CausalConv1d
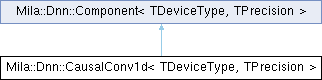
Inheritance diagram for Mila::Dnn::CausalConv1d< TDeviceType, TPrecision >:
Public Types | |
| using | ComponentBase = Component<TDeviceType, TPrecision> |
| using | MR = typename DeviceTypeTraits<TDeviceType>::memory_resource |
| using | StateSnapshot = Tensor<TensorDataType::FP32, CpuMemoryResource> |
| Where a snapshot of the retained rows lives: host memory, FP32, [B, K-1, C]. | |
| using | TensorType = Tensor<TPrecision, MR> |
Public Member Functions | |
| CausalConv1d (const std::string &name, const CausalConv1dConfig &config, std::optional< DeviceId > device_id=std::nullopt) | |
| TensorType & | decode (const TensorType &input, dim_t) |
| Convolve one token against the retained rows. | |
| DeviceId | getDeviceId () const override |
| Get the compute device id associated with this component. | |
| std::vector< ITensor * > | getGradients () const override |
| Return non-owning pointers to parameter gradient tensors. | |
| MemoryStats | getMemoryStats () const override |
| Return the current memory allocation breakdown for this component. | |
| std::vector< ObservableStage > | getObservableStages () const override |
| Stages this component publishes, and the passes each is published on. | |
| std::vector< const ITensor * > | getOutputs () const override |
| Return non-owning pointers to the tensors this component produces. | |
| std::vector< std::string > | getParameterNames () const override |
| List all available parameter names for this component. | |
| std::vector< ITensor * > | getParameters () const override |
| Return non-owning pointers to parameter tensors. | |
| MemoryStats | getRequiredMemory (const BuildContext &context) const override |
| Report what build( context ) would allocate, without allocating it. | |
| const ComponentType | getType () const override |
| Get the component type identifier. | |
| void | installSharedOutput (std::shared_ptr< TensorType > output) |
| Install a shared output slot (activation pooling). | |
| void | loadParameter (const std::string &name, const ITensorBlob &blob) override |
| Load a parameter from serialized tensor data. | |
| StateSnapshot | makeStateSnapshot () const |
| A snapshot sized for the built geometry. Allocates; hold it and reuse it. | |
| dim_t | parameterCount () const override |
| Return number of trainable parameters. | |
| TensorType & | prefill (const TensorType &input, dim_t position_offset) |
Convolve a chunk starting at position_offset. | |
| void | resetState () |
| Drop the retained rows. The next prefill starts a fresh sequence. | |
| void | restoreState (const StateSnapshot &source) |
| Replace the retained rows, and with them the fact that there ARE retained rows. | |
| void | save_ (ModelArchive &archive, SerializationMode) const override |
| void | saveFlatTensors (Serialization::SafeTensorsWriter &writer, const std::string &prefix, Serialization::TensorSavePass pass) const override |
| Drive this component's tensors through one pass of a flat safetensors save. | |
| void | snapshotState (StateSnapshot &destination) const |
| Copy the retained rows out. | |
| void | synchronize () override |
| Wait for outstanding device work submitted by this component. | |
| std::string | toString () const override |
| Produce a short, human-readable description of the component. | |
| Public Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| Component (const std::string &name) | |
| Construct component with required name identifier. | |
| virtual void | build (const BuildContext &context) final |
| Build the component with the provided BuildContext (canonical overload). | |
| IExecutionContext * | getExecutionContext () const |
| Get the shared execution context. | |
| const std::string | getName () const |
| Get the component's name identifier. | |
| Compute::ComputePassMask | getObservedPasses () const noexcept |
| RuntimeMode | getRuntimeMode () const noexcept |
| TrainingMode | getTrainingMode () const noexcept |
| The current runtime behavioral mode of this Component. | |
| virtual bool | isBuilt () const final |
| Returns true if build() has completed successfully. | |
| bool | isInferenceMode () const noexcept |
| bool | isTrainingMode () const noexcept |
| virtual void | load_ (ModelArchive &archive, SerializationMode mode) |
| Restore this component's parameters from its archive scope. | |
| virtual void | requireSerializableParameters () const |
| Verify this component can serialize whatever parameters it owns. | |
| void | setObservedPasses (Compute::ComputePassMask passes) noexcept |
| Select which passes this component publishes on. | |
| void | setTrainingMode (TrainingMode mode) |
| Set the runtime behavioral mode for this Component. | |
| virtual void | zeroGradients () |
| Clear all model-owned gradients for this component. | |
Protected Member Functions | |
| void | onBuilding (const BuildContext &build_context) override |
| Hook invoked by build() to allocate component buffers. | |
| void | onExecutionContextSet () override |
| Lifecycle hook: Called immediately after ExecutionContext is set. | |
| void | onTrainingModeChanging (TrainingMode) override |
| Hook called before TrainingMode transitions. | |
| Protected Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| bool | hasExecutionContext () const noexcept |
| Check if execution context has been set. | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | loadParameterFromBlob (const std::string ¶m_name, const Serialization::ITensorBlob &blob, Tensor< TParameterPrecision, TMemoryResource > &target, const shape_t &expected_shape) |
| Load a tensor blob into a parameter tensor with validation. | |
| void | publish (Compute::ComputePass pass, std::string_view stage, const ITensor &value) const |
| Publish one activation to the observer, if this pass is being observed. | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | saveParameterToArchive (ModelArchive &archive, const std::string ¶meter_name, const Tensor< TParameterPrecision, TMemoryResource > ¶meter) const |
| Write one parameter tensor into the archive under "tensors/<name>". | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | saveParameterToWriter (Serialization::SafeTensorsWriter &writer, const std::string &flat_name, const Tensor< TParameterPrecision, TMemoryResource > ¶meter, Serialization::TensorSavePass pass) const |
| Drive one parameter through one pass of a flat safetensors save. | |
| void | setExecutionContext (IExecutionContext *context) |
| Set the execution context for this component. | |
Additional Inherited Members | |
| Static Public Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| static constexpr DeviceType | getDeviceType () |
| Compile-time device type for this component instance. | |
| static constexpr TensorDataType | getPrecision () noexcept |
| Compile-time tensor precision for this component instance. | |
| Protected Types inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| using | HostStagingMemoryResource = typename DeviceTypeTraits<TDeviceType>::host_staging_memory_resource |
| Host memory a device-resident parameter stages through. | |
| Protected Attributes inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| BuildContext | build_context_ { shape_t{ 1 }, RuntimeMode::Training } |
| The BuildContext stored at build time. | |
Member Typedef Documentation
◆ StateSnapshot
template<DeviceType TDeviceType, TensorDataType TPrecision>
| using Mila::Dnn::CausalConv1d< TDeviceType, TPrecision >::StateSnapshot = Tensor<TensorDataType::FP32, CpuMemoryResource> |
Where a snapshot of the retained rows lives: host memory, FP32, [B, K-1, C].
FP32 REGARDLESS OF TPrecision, and still exact. BF16 is not a CPU storage type here, so a same-type host snapshot is not expressible; widening to FP32 is lossless because BF16 is a truncated FP32, and narrowing back returns the identical value because it is one the format holds. The cost is twice the bytes on a window of kernel_width - 1 rows, which is the small half of anything that carries one.
Member Function Documentation
◆ decode()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inline |
Convolve one token against the retained rows.
position is unused: unlike RoPE the convolution has no absolute notion of where it is, only of the K-1 rows behind it. It is in the signature so the call site reads like every other decode step, and so a caller cannot pass the two paths different notions of position.
◆ getDeviceId()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Get the compute device id associated with this component.
Must return the device on which parameters and operations execute.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getGradients()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Return non-owning pointers to parameter gradient tensors.
Gradient buffers are allocated only when the component is built in training mode, so a component built for inference returns an empty vector. Stateless components return empty in either mode. This is the accessor counterpart to getParameters() and does not throw on mode.
- Returns
- Vector of gradient pointers; empty when built for inference.
- Exceptions
-
std::runtime_error if called before the component has been built.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getMemoryStats()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Return the current memory allocation breakdown for this component.
Reflects allocations at the moment of the call. The returned stats naturally track the component lifecycle:
After construction – nothing; construction allocates none After build( Inference ) – parameters + T=1 state buffers After build( Training ) – parameters + T=full state buffers After setTrainingMode( Train ) – parameters + state + gradients
For CompositeComponent and Network, the returned stats are the recursive aggregate of all child components.
May be called at any time – no lifecycle preconditions.
- Returns
- MemoryStats reflecting current allocations.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getObservableStages()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Stages this component publishes, and the passes each is published on.
Lets a caller tell an uninstrumented component from a clean one before running anything. The pass qualifier is load-bearing rather than decorative: the stage set genuinely differs by pass, since a prefill can produce intermediates its decode never materializes.
- Returns
- Vector of stages; empty for components that publish nothing.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getOutputs()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Return non-owning pointers to the tensors this component produces.
The counterpart to getParameters(): that reports what a component HOLDS, this reports what it PRODUCES. Tensors are the built allocations, so their extents are the ceiling a forward pass may narrow within – an observer wanting the live value of a particular call receives it through publication instead.
An empty result means the component does not describe itself. That absence cannot be mistaken for a finding – a view renders no row for it – so no distinction beyond empty is offered.
- Returns
- Vector of output pointers; empty before build, and for undescribed components.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getParameterNames()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
List all available parameter names for this component.
Returns an empty vector by default. Leaf components with parameters should override to return their canonical parameter name list in the same stable order used by save_() and loadParameter().
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getParameters()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Return non-owning pointers to parameter tensors.
The returned tensor pointers remain valid for the lifetime of the component. Order should be canonical (weights before biases).
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getRequiredMemory()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Report what build( context ) would allocate, without allocating it.
The predictive counterpart to getMemoryStats(): what this component would need against what it currently has. Called on a constructed but unbuilt component, which is possible because construction commits no device memory – see Specifications/MemoryFootprint.md.
Implementations mirror their own onBuilding(), which is why the two take the same BuildContext: an implementation cannot answer for a different shape, runtime mode, or prefill size than the one build() would receive.
Composites mirror whatever their getMemoryStats() twin does – children, plus directly-owned buffers, minus any pooling, output-sharing or weight- tying correction. A plain sum over children overcounts wherever a buffer is installed rather than self-allocated.
- Parameters
-
context The context that would be passed to build().
- Returns
- MemoryStats the component would allocate.
- Exceptions
-
std::logic_error if this component has not implemented the contract.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getType()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Get the component type identifier.
Used for serialization and runtime type identification.
- Returns
- Component type enum value.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ installSharedOutput()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inline |
Install a shared output slot (activation pooling).
Before build().
◆ loadParameter()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Load a parameter from serialized tensor data.
Loads raw tensor bytes directly into an existing parameter tensor, handling precision conversion and device upload as needed.
The component validates that the blob's shape matches the parameter's expected shape, then delegates to the backend to perform:
- Precision conversion (blob dtype -> parameter dtype)
- Device upload (CPU bytes -> target device)
Takes the parameter name used to locate the target tensor, and a blob holding serialized tensor metadata and raw bytes.
- Exceptions
-
std::runtime_error if component has no parameters to load. std::runtime_error if blob shape doesn't match parameter shape.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ onBuilding()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverrideprotectedvirtual |
Hook invoked by build() to allocate component buffers.
Receives the stored BuildContext. Implementations must use config.allocationSeqLen() when sizing output buffers – this is the single call that makes Inference and Training allocate the correct buffer sizes automatically without per-component logic.
// Example -- Linear component:
shape_t out_shape =
{
config.batchSize(),
config.allocationSeqLen(), // 1 for Inference, T for Training
config_.getOutputFeatures()
};
output_ = std::make_unique<TensorType>( device, out_shape,
this->getName() + ".output" );
TensorShape shape_t
Row-major shape descriptor for tensor dimensional sizes.
Definition Tensor.Types.ixx:173
const std::string getName() const
Get the component's name identifier.
Definition Component.ixx:522
The default implementation forwards to the legacy onBuilding( const shape_t& ) overload for backwards compatibility. New components should override this overload directly.
- Note
- Do not call build() or onBuilding() from within this hook.
- Implementations should either succeed fully or leave no partial state, as a failed build() may be retried.
Takes the build-time configuration; use its allocationSeqLen() to obtain the correct output buffer sequence dimension.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ onExecutionContextSet()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverrideprotectedvirtual |
Lifecycle hook: Called immediately after ExecutionContext is set.
Override this to perform initialization that requires a valid ExecutionContext. At the time this is called, getExecutionContext() is guaranteed to return a valid context.
Common uses:
- Composite components: Create and configure child components.
- Device resource allocation: Query device capabilities.
Default implementation does nothing.
- Exceptions
-
Any exception thrown will cause setExecutionContext() to fail and restore the component to a "context not set" state.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ onTrainingModeChanging()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverrideprotectedvirtual |
Hook called before TrainingMode transitions.
Called by setTrainingMode() after validation and lock acquisition, before the internal state is updated. Derived classes override to respond to the transition – e.g. zeroing gradient buffers on transition to Eval, or re-enabling dropout on transition to Training.
The default implementation is a no-op.
Takes the incoming TrainingMode.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ parameterCount()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Return number of trainable parameters.
For leaf components this is the element count of owned parameter tensors. CompositeComponent and Network implementations should return the recursive aggregate across all children.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ prefill()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inline |
Convolve a chunk starting at position_offset.
At offset 0 the sequence starts here and the left context is zero; past that the retained rows supply it. Refreshes the state on the way out.
◆ save_()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ saveFlatTensors()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Drive this component's tensors through one pass of a flat safetensors save.
This is the path save_() cannot serve. A quantized weight is packed storage plus a scale companion and ModelArchive has no representation for that pairing, so save_() refuses it; the flat container expresses it as sibling tensors and this writes them.
The vocabulary is the flat format's: a fully qualified dotted component path plus a parameter name, exactly what loadParameters() parses on the way back in. Composites contribute nothing themselves – they recurse and extend the prefix – so the emitted set matches what the reader will route back through loadParameter().
Concrete parameter types, not ITensor, on purpose: a type-erased walk would have to ask at runtime whether a tensor's memory is host-accessible, and MemoryResource::is_host_accessible is a compile-time constant. Keeping concrete types here is what avoids widening an exported core type for a serialization concern.
The default refuses rather than writing nothing. A component that owns parameters and does not implement this would otherwise contribute silently to an artifact that loads, runs, and produces garbage – the same failure mode Phase 0 removed from save_().
- Parameters
-
writer Writer being driven. prefix Fully qualified component path, e.g. "tf_layer_0.qkv_proj". pass Declare reserves byte ranges; Write streams bytes in declaration order.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ snapshotState()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inline |
Copy the retained rows out.
REFUSES AN UNPRIMED WINDOW, and that refusal is the whole reason the primed flag does not need to appear in the snapshot. The rows are meaningless before a chunk has been seen – they are zeros standing for a left context that never existed – so a snapshot taken then would restore into a component that believes it has history and convolves against nothing. Rather than carry a flag alongside every snapshot for a case that is always a caller error, a snapshot is only obtainable when it means something, and restoring one always primes.
◆ synchronize()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Wait for outstanding device work submitted by this component.
On CPU this may be a no-op. Use to ensure results are visible to the host or to measure synchronous timings.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ toString()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Produce a short, human-readable description of the component.
Implementations should keep output concise and avoid throwing.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
The documentation for this class was generated from the following file:
- Mila/Src/Dnn/Components/Convolutions/CausalConv1d.ixx
