Loading...
Searching...
No Matches
Mila::Dnn::GatedMLP< TDeviceType, TPrecision, TGate, TWeightQuantization > Class Template Referenceexport
module Dnn.Components.GatedMLP
Gated feed-forward (GatedMLP) composite component. More...
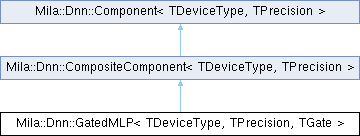
Inheritance diagram for Mila::Dnn::GatedMLP< TDeviceType, TPrecision, TGate, TWeightQuantization >:
Public Types | |
| using | ComponentPtr = typename CompositeComponentBase::ComponentPtr |
| using | CompositeComponentBase = CompositeComponent<TDeviceType, TPrecision> |
| using | LinearType = Linear<TDeviceType, TPrecision, TWeightQuantization> |
| using | MR = typename DeviceTypeTraits<TDeviceType>::memory_resource |
| using | SwigluType = Swiglu<TDeviceType, TPrecision, TGate> |
| using | TensorType = Tensor<TPrecision, MR> |
| Public Types inherited from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision > | |
| using | ComponentBase = Component<TDeviceType, TPrecision> |
| using | ComponentPtr = std::shared_ptr<Component<TDeviceType, TPrecision>> |
Public Member Functions | |
| GatedMLP (const std::string &name, const GatedMLPConfig &config, std::optional< DeviceId > device_id=std::nullopt) | |
| TensorType & | backward (const TensorType &input, const TensorType &output_grad) |
| TensorType & | decode (const TensorType &input) const |
| Single-token inference convenience with no gradient capture. | |
| TensorType & | forward (const TensorType &input) |
| Forward pass: fc_gate_up -> gate -> fc_down. | |
| MemoryStats | getMemoryStats () const override |
| Return the current memory allocation breakdown for this component. | |
| std::vector< ObservableStage > | getObservableStages () const override |
| Stages this component publishes, and the passes each is published on. | |
| MemoryStats | getRequiredMemory (const BuildContext &context) const override |
| What onBuilding() would allocate for this context, without allocating. | |
| const ComponentType | getType () const override |
| Get the component type identifier. | |
| void | installSharedOutputs (std::shared_ptr< TensorType > gate_up_output, std::shared_ptr< TensorType > gate_output, std::shared_ptr< TensorType > down_output) |
| Install shared output slots into the three children (activation pooling). | |
| std::string | toString () const override |
| Generate a human-readable description. | |
| void | zeroGradients () override |
| Clear all model-owned gradients for this component. | |
| Public Member Functions inherited from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision > | |
| CompositeComponent (CompositeComponent &&) noexcept=default | |
| CompositeComponent (const CompositeComponent &)=delete | |
| CompositeComponent (const std::string &name) | |
| Construct composite component with name. | |
| CompositeComponent & | addComponent (ComponentPtr component) |
| Add a pre-constructed child component (chainable). | |
| size_t | childCount () const noexcept |
| Get the number of direct children. | |
| void | clearComponents () |
| Clear all child components. | |
| std::vector< std::string > | componentPaths () const |
| Every component path in this subtree, in traversal order. | |
| ComponentPtr | findComponent (const std::string &path) const |
| Resolve a dot-separated component path within this composite. | |
| ComponentPtr | getComponent (const std::string &name) const |
| Retrieve a direct child component by name. | |
| const std::vector< ComponentPtr > & | getComponents () const |
| Get all child components in insertion order. | |
| DeviceId | getDeviceId () const override |
| Get the compute device for this composite. | |
| std::vector< ITensor * > | getGradients () const override |
| Get all parameter gradients from all children. | |
| std::vector< ITensor * > | getParameters () const override |
| Get all parameters from all children. | |
| bool | hasChildren () const noexcept |
| Check if this composite has any children. | |
| bool | hasComponent (const std::string &name) const |
| Check if a named child component exists. | |
| size_t | observe (std::string_view pattern, Compute::ComputePassMask passes, Compute::ActivationObserver sink) |
| Attach sink to every component in this subtree whose path matches. | |
| CompositeComponent & | operator= (CompositeComponent &&) noexcept=default |
| CompositeComponent & | operator= (const CompositeComponent &)=delete |
| dim_t | parameterCount () const override |
| Count parameters across all children. | |
| bool | removeComponent (const std::string &name) |
| Remove a child component by name. | |
| void | saveFlatTensors (Serialization::SafeTensorsWriter &writer, const std::string &prefix, Serialization::TensorSavePass pass) const override |
| Recurse into children, extending the flat dotted prefix. | |
| void | stopObserving () |
| Detach every observer in this subtree and clear the shared sink. | |
| void | synchronize () override |
| Synchronize all child components. | |
| ComponentPtr | tryFindComponent (const std::string &path) const |
| Try to resolve a dot-separated component path within this composite. | |
| Public Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| Component (const std::string &name) | |
| Construct component with required name identifier. | |
| virtual void | build (const BuildContext &context) final |
| Build the component with the provided BuildContext (canonical overload). | |
| IExecutionContext * | getExecutionContext () const |
| Get the shared execution context. | |
| const std::string | getName () const |
| Get the component's name identifier. | |
| Compute::ComputePassMask | getObservedPasses () const noexcept |
| virtual std::vector< const ITensor * > | getOutputs () const |
| Return non-owning pointers to the tensors this component produces. | |
| virtual std::vector< std::string > | getParameterNames () const |
| List all available parameter names for this component. | |
| RuntimeMode | getRuntimeMode () const noexcept |
| TrainingMode | getTrainingMode () const noexcept |
| The current runtime behavioral mode of this Component. | |
| virtual bool | isBuilt () const final |
| Returns true if build() has completed successfully. | |
| bool | isInferenceMode () const noexcept |
| bool | isTrainingMode () const noexcept |
| virtual void | loadParameter (const std::string &, const Serialization::ITensorBlob &) |
| Load a parameter from serialized tensor data. | |
| void | setObservedPasses (Compute::ComputePassMask passes) noexcept |
| Select which passes this component publishes on. | |
| void | setTrainingMode (TrainingMode mode) |
| Set the runtime behavioral mode for this Component. | |
Protected Member Functions | |
| void | onBuilding (const BuildContext &context) override |
| Build child graph with the gated shape contract. | |
| void | onTrainingModeChanging (TrainingMode training_mode) override |
| Hook invoked when training mode is about to change. | |
| Protected Member Functions inherited from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision > | |
| template<typename TComponent> | |
| std::shared_ptr< TComponent > | getComponentAs (const std::string &name) const |
| Retrieve a typed child component by name. | |
| void | load_ (ModelArchive &archive, SerializationMode mode) override |
| Restore children from their nested scopes, mirroring save_(). | |
| void | onExecutionContextSet () override |
| Hook invoked after ExecutionContext is set. | |
| virtual void | optimize () |
| Virtual hook for graph optimization after construction. | |
| void | requireSerializableParameters () const override |
| No-op override: a composite names no parameters of its own. | |
| void | save_ (ModelArchive &archive, SerializationMode mode) const override |
| Protected Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| bool | hasExecutionContext () const noexcept |
| Check if execution context has been set. | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | loadParameterFromBlob (const std::string ¶m_name, const Serialization::ITensorBlob &blob, Tensor< TParameterPrecision, TMemoryResource > &target, const shape_t &expected_shape) |
| Load a tensor blob into a parameter tensor with validation. | |
| void | publish (Compute::ComputePass pass, std::string_view stage, const ITensor &value) const |
| Publish one activation to the observer, if this pass is being observed. | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | saveParameterToArchive (ModelArchive &archive, const std::string ¶meter_name, const Tensor< TParameterPrecision, TMemoryResource > ¶meter) const |
| Write one parameter tensor into the archive under "tensors/<name>". | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | saveParameterToWriter (Serialization::SafeTensorsWriter &writer, const std::string &flat_name, const Tensor< TParameterPrecision, TMemoryResource > ¶meter, Serialization::TensorSavePass pass) const |
| Drive one parameter through one pass of a flat safetensors save. | |
| void | setExecutionContext (IExecutionContext *context) |
| Set the execution context for this component. | |
Additional Inherited Members | |
| Static Public Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| static constexpr DeviceType | getDeviceType () |
| Compile-time device type for this component instance. | |
| static constexpr TensorDataType | getPrecision () noexcept |
| Compile-time tensor precision for this component instance. | |
| Protected Types inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| using | HostStagingMemoryResource = typename DeviceTypeTraits<TDeviceType>::host_staging_memory_resource |
| Host memory a device-resident parameter stages through. | |
| Protected Attributes inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| BuildContext | build_context_ { shape_t{ 1 }, RuntimeMode::Training } |
| The BuildContext stored at build time. | |
Detailed Description
template<DeviceType TDeviceType, TensorDataType TPrecision, ActivationType TGate = ActivationType::Silu, WeightQuantPolicy TWeightQuantization = NoWeightQuant>
requires PrecisionSupportedOnDevice<TPrecision, TDeviceType>
class Mila::Dnn::GatedMLP< TDeviceType, TPrecision, TGate, TWeightQuantization >
requires PrecisionSupportedOnDevice<TPrecision, TDeviceType>
class Mila::Dnn::GatedMLP< TDeviceType, TPrecision, TGate, TWeightQuantization >
Gated feed-forward (GatedMLP) composite component.
Device-templated composite implementing the GLU (Gated Linear Unit) family of gated FFNs – SwiGLU (Llama, Qwen) and GeGLU (Gemma) – and the single-expert reference for a future MoE layer: Input -> fc_gate_up Linear(in -> 2H, fused) -> Swiglu gate (2H -> H) -> fc_down Linear(H -> in) -> Output
The gate multiplies TGate(gate half) by the up half: SiLU gives SwiGLU, GELU gives GeGLU. Both projections carry TWeightQuantization; the gate has no weights.
MoE-readiness seams (FfnAndMoE.md s9): the injected-context path is the norm (owned-context construction is a standalone convenience); forward operates on the trailing feature dimension so it is valid for both [B, T, in] and gathered [num_tokens, in] layouts.
Member Function Documentation
◆ forward()
template<DeviceType TDeviceType, TensorDataType TPrecision, ActivationType TGate = ActivationType::Silu, WeightQuantPolicy TWeightQuantization = NoWeightQuant>
|
inline |
Forward pass: fc_gate_up -> gate -> fc_down.
Captures non-owning pointers to child-owned intermediates for backward().
- Parameters
-
input Input tensor [..., in_features].
- Returns
- Reference to the final fc_down output (owned by that child).
◆ getMemoryStats()
template<DeviceType TDeviceType, TensorDataType TPrecision, ActivationType TGate = ActivationType::Silu, WeightQuantPolicy TWeightQuantization = NoWeightQuant>
|
inlineoverridevirtual |
Return the current memory allocation breakdown for this component.
Reflects allocations at the moment of the call. The returned stats naturally track the component lifecycle:
After construction – nothing; construction allocates none After build( Inference ) – parameters + T=1 state buffers After build( Training ) – parameters + T=full state buffers After setTrainingMode( Train ) – parameters + state + gradients
For CompositeComponent and Network, the returned stats are the recursive aggregate of all child components.
May be called at any time – no lifecycle preconditions.
- Returns
- MemoryStats reflecting current allocations.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getObservableStages()
template<DeviceType TDeviceType, TensorDataType TPrecision, ActivationType TGate = ActivationType::Silu, WeightQuantPolicy TWeightQuantization = NoWeightQuant>
|
inlineoverridevirtual |
Stages this component publishes, and the passes each is published on.
Lets a caller tell an uninstrumented component from a clean one before running anything. The pass qualifier is load-bearing rather than decorative: the stage set genuinely differs by pass, since a prefill can produce intermediates its decode never materializes.
- Returns
- Vector of stages; empty for components that publish nothing.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getRequiredMemory()
template<DeviceType TDeviceType, TensorDataType TPrecision, ActivationType TGate = ActivationType::Silu, WeightQuantPolicy TWeightQuantization = NoWeightQuant>
|
inlineoverridevirtual |
What onBuilding() would allocate for this context, without allocating.
Each child is sized at its own width rather than the generic recursion's single shape, exactly as onBuilding() builds it. Installed outputs are excluded by the children themselves, from their own installed flag or the context's.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getType()
template<DeviceType TDeviceType, TensorDataType TPrecision, ActivationType TGate = ActivationType::Silu, WeightQuantPolicy TWeightQuantization = NoWeightQuant>
|
inlineoverridevirtual |
Get the component type identifier.
Used for serialization and runtime type identification.
- Returns
- Component type enum value.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ installSharedOutputs()
template<DeviceType TDeviceType, TensorDataType TPrecision, ActivationType TGate = ActivationType::Silu, WeightQuantPolicy TWeightQuantization = NoWeightQuant>
|
inline |
Install shared output slots into the three children (activation pooling).
Must be called before build(). Each slot is owned and memory-accounted by the installer, and must cover this component's build shape at its own width: [..., 2H] for the gate+up projection, [..., H] for the gate, [..., in] for the down projection. A pooling caller declares the same intent to getRequiredMemory() through BuildContext::withInstalledOutput().
◆ onBuilding()
template<DeviceType TDeviceType, TensorDataType TPrecision, ActivationType TGate = ActivationType::Silu, WeightQuantPolicy TWeightQuantization = NoWeightQuant>
|
inlineoverrideprotectedvirtual |
Build child graph with the gated shape contract.
fc_gate_up receives the input shape; the gate and fc_down receive the fused 2H and the gated H shapes respectively. The child contexts are derived with withShape so the prefill size, the installed-output declaration and the parameter-initialization choice reach the children unchanged.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ onTrainingModeChanging()
template<DeviceType TDeviceType, TensorDataType TPrecision, ActivationType TGate = ActivationType::Silu, WeightQuantPolicy TWeightQuantization = NoWeightQuant>
|
inlineoverrideprotectedvirtual |
Hook invoked when training mode is about to change.
Propagates the new mode to all child components. The hook runs with the Component's training mutex held; it MUST NOT call setTrainingMode().
- Parameters
-
training_mode New training mode (Normal or Eval)
Reimplemented from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision >.
◆ toString()
template<DeviceType TDeviceType, TensorDataType TPrecision, ActivationType TGate = ActivationType::Silu, WeightQuantPolicy TWeightQuantization = NoWeightQuant>
|
inlineoverridevirtual |
Generate a human-readable description.
- Returns
- String representation showing children
Reimplemented from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision >.
◆ zeroGradients()
template<DeviceType TDeviceType, TensorDataType TPrecision, ActivationType TGate = ActivationType::Silu, WeightQuantPolicy TWeightQuantization = NoWeightQuant>
|
inlineoverridevirtual |
Clear all model-owned gradients for this component.
Default implementation is a no-op. Composite components should override to recurse to children. Leaf components should override to zero their parameter and activation gradients using device-aware helpers.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
The documentation for this class was generated from the following file:
- Mila/Src/Dnn/Components/FFN/GatedMLP/GatedMLP.ixx
