Loading...
Searching...
No Matches
Mila::Dnn::LlamaModel< TDeviceType, TPrecision > Class Template Referenceexport
module Dnn.Models.LlamaModel
LLaMA 3 compatible inference model. More...
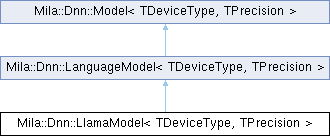
Inheritance diagram for Mila::Dnn::LlamaModel< TDeviceType, TPrecision >:
Public Types | |
| using | LlamaKvPolicy = Quant::KvCache::NoKvCompression |
| KV policy for the Llama chassis. | |
| using | ModelBase = LanguageModel<TDeviceType, TPrecision> |
| using | MR = typename DeviceTypeTraits<TDeviceType>::memory_resource |
| using | StagingMR = CpuMemoryResource |
| using | TensorType = Tensor<TPrecision, MR> |
| using | TokenIndexType = Tensor<dtype_t::INT32, MR> |
| Public Types inherited from Mila::Dnn::LanguageModel< TDeviceType, TPrecision > | |
| using | Base = Model<TDeviceType, TPrecision> |
| Public Types inherited from Mila::Dnn::Model< TDeviceType, TPrecision > | |
| using | NetworkType = Network<TDeviceType, TPrecision> |
Public Member Functions | |
| LlamaModel (const LlamaModel &)=delete | |
| LlamaModel (LlamaModel &&)=default | |
| const LlamaConfig & | getConfig () const noexcept |
| LlamaModel & | operator= (const LlamaModel &)=delete |
| LlamaModel & | operator= (LlamaModel &&)=default |
| std::string | toString () const override |
| Human-readable summary of this model's configuration. | |
| Public Member Functions inherited from Mila::Dnn::LanguageModel< TDeviceType, TPrecision > | |
| LanguageModel (const LanguageModel &)=delete | |
| LanguageModel (LanguageModel &&)=default | |
| std::vector< std::string > | componentPaths () const |
| Every observable component path, for choosing a pattern or diagnosing a zero. | |
| GenerateStatus | generate (std::span< const int32_t > prompt_tokens, const std::function< void(int32_t)> &on_token, const GenerateParams ¶ms={}, std::stop_token stop={}) |
| Generate tokens from a prompt, streaming each through on_token. | |
| size_t | observe (std::string_view pattern, Compute::ComputePassMask passes, Compute::ActivationObserver sink) |
| Watch activations flowing through matching components on matching passes. | |
| LanguageModel & | operator= (const LanguageModel &)=delete |
| LanguageModel & | operator= (LanguageModel &&)=default |
| void | save (const std::filesystem::path &path) const |
| Write this model's live weights as a safetensors weights file. | |
| void | seedSampler (uint64_t seed) |
| Seed the sampler's RNG for reproducible generation. | |
| void | stopObserving () |
| Detach every observer and clear the sink. A probe that outlives its question costs. | |
| std::string | weightQuantizationScheme () const |
| The scheme name save records for these weights, e.g. | |
| Public Member Functions inherited from Mila::Dnn::Model< TDeviceType, TPrecision > | |
| Model (const Model &)=delete | |
| Model (Model &&)=default | |
| DeviceId | getDeviceId () const noexcept |
| The device this model runs on. | |
| MemoryStats | getMemoryStats () const |
| Current memory allocation breakdown for this model. | |
| RuntimeMode | getRuntimeMode () const noexcept |
| The runtime mode this model was constructed for. | |
| bool | isEval () const noexcept |
| True if this model is currently in eval sub-state. | |
| bool | isInferenceMode () const noexcept |
| True if this model was constructed for inference. | |
| bool | isTrainingMode () const noexcept |
| True if this model was constructed for training. | |
| Model & | operator= (const Model &)=delete |
| Model & | operator= (Model &&)=default |
| void | setEval (bool eval) |
| Toggle eval sub-state for this model. | |
| void | train () |
| Run the training loop for this model. | |
Static Public Member Functions | |
| static DeploymentFootprint | getDeploymentFootprint (const std::filesystem::path &path, const LlamaModelConfig &model_config, DeviceId device_id=DeviceId{ TDeviceType, 0 }) |
| The same prediction, plus how this deployment would chunk its prefill. | |
| static MemoryStats | getRequiredMemory (const std::filesystem::path &path, const LlamaModelConfig &model_config, DeviceId device_id=DeviceId{ TDeviceType, 0 }) |
| What loading this checkpoint at this context length would cost in VRAM. | |
| static std::unique_ptr< LlamaModel< TDeviceType, TPrecision > > | load (const std::filesystem::path &path, const LlamaModelConfig &model_config, DeviceId device_id=DeviceId{ TDeviceType, 0 }) |
| Load Llama from a Mila weights file. | |
Protected Member Functions | |
| dim_t | maxSequenceLength () const noexcept override |
| Maximum sequence length from LLaMA config. | |
| GenerateStatus | onGenerating (std::span< const int32_t > prompt_tokens, const std::function< void(int32_t)> &on_token, const GenerateParams ¶ms, std::stop_token stop) override |
| Prefill + KV-cache decode loop with per-token streaming. | |
| void | onTraining () override |
| Training loop – not yet implemented for LlamaModel. | |
| dim_t | vocabSize () const noexcept override |
| Vocabulary size from LLaMA config. | |
| Protected Member Functions inherited from Mila::Dnn::LanguageModel< TDeviceType, TPrecision > | |
| LanguageModel (std::unique_ptr< LanguageModelNetwork< TDeviceType, TPrecision > > network, RuntimeMode runtime_mode, Serialization::WeightsMetadata source_metadata={}, WeightQuantization weight_quantization=WeightQuantization::None, int fp4_group_size=128) | |
| int32_t | awaitSampledToken () |
| Block until the last enqueueSampleNext()'s token id is host-visible. | |
| void | enqueueSampleNext (const TensorType &logits, TokenTensor &token_out, const SamplingParams ¶ms) |
| Enqueue a sampling step without waiting for the host readback. | |
| virtual float | finalLogitSoftcap () const noexcept |
| Optional final-logit softcap the sampler applies (0 disables). | |
| const LanguageModelNetwork< TDeviceType, TPrecision > & | getNetwork () const noexcept |
| LanguageModelNetwork< TDeviceType, TPrecision > & | getNetwork () noexcept |
| int32_t | sampleNext (const TensorType &logits, TokenTensor &token_out, const SamplingParams ¶ms) |
| Sample the next token from a logits row on the device. | |
| Protected Member Functions inherited from Mila::Dnn::Model< TDeviceType, TPrecision > | |
| Model (std::unique_ptr< NetworkType > network, RuntimeMode runtime_mode) | |
| Construct with a fully built network and runtime mode. | |
Additional Inherited Members | |
| Protected Types inherited from Mila::Dnn::LanguageModel< TDeviceType, TPrecision > | |
| using | MR = typename DeviceTypeTraits<TDeviceType>::memory_resource |
| using | TensorType = Tensor<TPrecision, MR> |
| using | TokenTensor = Tensor<TensorDataType::INT32, MR> |
| Protected Attributes inherited from Mila::Dnn::LanguageModel< TDeviceType, TPrecision > | |
| int | fp4_group_size_ { 128 } |
| The FP4 group the live weights were built at; meaningful only when they are FP4. | |
| Serialization::WeightsMetadata | source_metadata_ |
| The loaded weights file's metadata, carried so save can write it back verbatim. | |
| WeightQuantization | weight_quantization_ { WeightQuantization::None } |
| What the live weights are, not what the source file was. | |
| Protected Attributes inherited from Mila::Dnn::Model< TDeviceType, TPrecision > | |
| std::unique_ptr< NetworkType > | network_ |
| The owned Network instance. | |
Detailed Description
template<DeviceType TDeviceType, TensorDataType TPrecision>
requires PrecisionSupportedOnDevice<TPrecision, TDeviceType>
class Mila::Dnn::LlamaModel< TDeviceType, TPrecision >
requires PrecisionSupportedOnDevice<TPrecision, TDeviceType>
class Mila::Dnn::LlamaModel< TDeviceType, TPrecision >
LLaMA 3 compatible inference model.
Owns a loaded, built LlamaTransformer and exposes generate() for autoregressive text generation. Supports the prefill + KV-cache decode two-phase generation loop.
Construction is only possible via load(). The network is always in a built, weights-loaded, inference-mode state when generation is called.
Thread safety: not thread-safe; external synchronization required if shared.
Member Typedef Documentation
◆ LlamaKvPolicy
template<DeviceType TDeviceType, TensorDataType TPrecision>
| using Mila::Dnn::LlamaModel< TDeviceType, TPrecision >::LlamaKvPolicy = Quant::KvCache::NoKvCompression |
KV policy for the Llama chassis.
Every Llama layer is full-attention, so there is no sliding window to bound a ring against and the cache spans the whole context. Class scope rather than per-function so the load and footprint paths cannot be pointed at different policies – that would make a model report a figure for a cache it does not build.
Member Function Documentation
◆ getDeploymentFootprint()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlinestatic |
The same prediction, plus how this deployment would chunk its prefill.
One graph construction answers both, because they are two readings of the same arithmetic – the chunk is resolved on the way to sizing the attention scratch getRequiredMemory reports, and was previously discarded there.
The second half is what a caller choosing a context length needs and memory alone cannot tell it: the scratch cost per chunk row carries a 2 * context_length term, so a longer context buys a smaller chunk. See Specifications/ChatConfiguration.md section 6.
- Exceptions
-
std::invalid_argument on device type mismatch or zero context length. std::runtime_error on an unreadable artifact or unsupported quantization.
◆ getRequiredMemory()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlinestatic |
What loading this checkpoint at this context length would cost in VRAM.
Reads the artifact header for geometry and constructs the graph, then reports what build() would allocate – without building it and without reading a weight. Returns measurements only; the fits/does-not verdict is adaptor policy. See Specifications/MemoryFootprint.md.
- Exceptions
-
std::invalid_argument on device type mismatch or zero context length. std::runtime_error on an unreadable artifact or unsupported quantization.
◆ load()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlinestatic |
Load Llama from a Mila weights file.
Reads a Mila weights file (e.g. converted from a HuggingFace LLaMA checkpoint) via WeightsReader. The network is built at the context length specified in model_config so RoPE embeddings and KV cache buffers cover the full range.
The model_config carries all deployment decisions:
- context_length – maximum sequence length to build for
- weight_quantization – compile-time dispatch to quantized or BF16 path
- kv_cache_compression – compile-time dispatch to KV cache policy
- Parameters
-
path Path to the Llama weights file. model_config Deployment configuration for this load. device_id Target device; must match TDeviceType.
- Returns
- Inference-ready LlamaModel.
- Exceptions
-
std::invalid_argument on device type mismatch or zero context length. std::runtime_error on load or parameter binding failure. std::runtime_error if model_config requests unsupported quantization (e.g. FP4).
◆ maxSequenceLength()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverrideprotectedvirtualnoexcept |
Maximum sequence length from LLaMA config.
Implements Mila::Dnn::LanguageModel< TDeviceType, TPrecision >.
◆ onGenerating()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverrideprotectedvirtual |
Prefill + KV-cache decode loop with per-token streaming.
Phase 1 (prefill): runs the full prompt through prefill() to populate the KV cache and samples the first new token from the last position. Phase 2 (decode): iterates one token at a time until max_new_tokens is reached, EOS is emitted, or stop is requested.
on_token is called for every generated token except EOS.
- Parameters
-
prompt_tokens Input token ids; truncated from the start if they exceed the model's max sequence length. on_token Callback invoked once per generated token (not EOS). params Per-call generation parameters (loop bound + sampling). stop Stop token for cooperative cancellation.
- Returns
- Why generation stopped.
Implements Mila::Dnn::LanguageModel< TDeviceType, TPrecision >.
◆ onTraining()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverrideprotectedvirtual |
Training loop – not yet implemented for LlamaModel.
- Exceptions
-
std::runtime_error always.
Implements Mila::Dnn::Model< TDeviceType, TPrecision >.
◆ toString()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverridevirtual |
Human-readable summary of this model's configuration.
Implements Mila::Dnn::Model< TDeviceType, TPrecision >.
◆ vocabSize()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineoverrideprotectedvirtualnoexcept |
Vocabulary size from LLaMA config.
Implements Mila::Dnn::LanguageModel< TDeviceType, TPrecision >.
The documentation for this class was generated from the following file:
- Mila/Src/Dnn/Models/LlaMa/LlamaModel.ixx
