Loading...
Searching...
No Matches
Mila::Dnn::LanguageModel< TDeviceType, TPrecision > Class Template Referenceabstractexport
module Dnn.LanguageModel
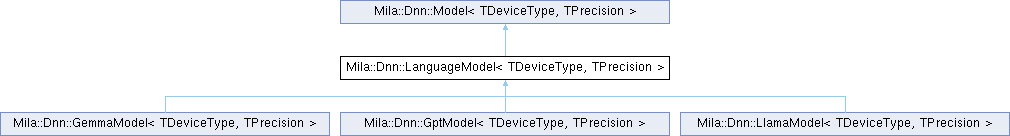
Inheritance diagram for Mila::Dnn::LanguageModel< TDeviceType, TPrecision >:
Public Types | |
| using | Base = Model<TDeviceType, TPrecision> |
| Public Types inherited from Mila::Dnn::Model< TDeviceType, TPrecision > | |
| using | NetworkType = Network<TDeviceType, TPrecision> |
Public Member Functions | |
| LanguageModel (const LanguageModel &)=delete | |
| LanguageModel (LanguageModel &&)=default | |
| std::vector< std::string > | componentPaths () const |
| Every observable component path, for choosing a pattern or diagnosing a zero. | |
| GenerateStatus | generate (std::span< const int32_t > prompt_tokens, const std::function< void(int32_t)> &on_token, const GenerateParams ¶ms={}, std::stop_token stop={}) |
| Generate tokens from a prompt, streaming each through on_token. | |
| size_t | observe (std::string_view pattern, Compute::ComputePassMask passes, Compute::ActivationObserver sink) |
| Watch activations flowing through matching components on matching passes. | |
| LanguageModel & | operator= (const LanguageModel &)=delete |
| LanguageModel & | operator= (LanguageModel &&)=default |
| void | save (const std::filesystem::path &path) const |
| Write this model's live weights as a safetensors weights file. | |
| void | seedSampler (uint64_t seed) |
| Seed the sampler's RNG for reproducible generation. | |
| void | stopObserving () |
| Detach every observer and clear the sink. A probe that outlives its question costs. | |
| std::string | weightQuantizationScheme () const |
| The scheme name save records for these weights, e.g. | |
| Public Member Functions inherited from Mila::Dnn::Model< TDeviceType, TPrecision > | |
| Model (const Model &)=delete | |
| Model (Model &&)=default | |
| DeviceId | getDeviceId () const noexcept |
| The device this model runs on. | |
| MemoryStats | getMemoryStats () const |
| Current memory allocation breakdown for this model. | |
| RuntimeMode | getRuntimeMode () const noexcept |
| The runtime mode this model was constructed for. | |
| bool | isEval () const noexcept |
| True if this model is currently in eval sub-state. | |
| bool | isInferenceMode () const noexcept |
| True if this model was constructed for inference. | |
| bool | isTrainingMode () const noexcept |
| True if this model was constructed for training. | |
| Model & | operator= (const Model &)=delete |
| Model & | operator= (Model &&)=default |
| void | setEval (bool eval) |
| Toggle eval sub-state for this model. | |
| virtual std::string | toString () const =0 |
| Human-readable summary of this model's configuration. | |
| void | train () |
| Run the training loop for this model. | |
Protected Types | |
| using | MR = typename DeviceTypeTraits<TDeviceType>::memory_resource |
| using | TensorType = Tensor<TPrecision, MR> |
| using | TokenTensor = Tensor<TensorDataType::INT32, MR> |
Protected Member Functions | |
| LanguageModel (std::unique_ptr< LanguageModelNetwork< TDeviceType, TPrecision > > network, RuntimeMode runtime_mode, Serialization::WeightsMetadata source_metadata={}, WeightQuantization weight_quantization=WeightQuantization::None, int fp4_group_size=128) | |
| int32_t | awaitSampledToken () |
| Block until the last enqueueSampleNext()'s token id is host-visible. | |
| void | enqueueSampleNext (const TensorType &logits, TokenTensor &token_out, const SamplingParams ¶ms) |
| Enqueue a sampling step without waiting for the host readback. | |
| virtual int32_t | eosToken () const noexcept=0 |
| virtual float | finalLogitSoftcap () const noexcept |
| Optional final-logit softcap the sampler applies (0 disables). | |
| const LanguageModelNetwork< TDeviceType, TPrecision > & | getNetwork () const noexcept |
| LanguageModelNetwork< TDeviceType, TPrecision > & | getNetwork () noexcept |
| virtual dim_t | maxSequenceLength () const noexcept=0 |
| virtual GenerateStatus | onGenerating (std::span< const int32_t > prompt_tokens, const std::function< void(int32_t)> &on_token, const GenerateParams ¶ms, std::stop_token stop)=0 |
| Prefill + decode implementation hook. | |
| int32_t | sampleNext (const TensorType &logits, TokenTensor &token_out, const SamplingParams ¶ms) |
| Sample the next token from a logits row on the device. | |
| virtual std::unordered_set< int32_t > | stopTokens () const |
| virtual dim_t | vocabSize () const noexcept=0 |
| Protected Member Functions inherited from Mila::Dnn::Model< TDeviceType, TPrecision > | |
| Model (std::unique_ptr< NetworkType > network, RuntimeMode runtime_mode) | |
| Construct with a fully built network and runtime mode. | |
| virtual void | onTraining ()=0 |
| Training loop hook – derived class owns the implementation. | |
Protected Attributes | |
| int | fp4_group_size_ { 128 } |
| The FP4 group the live weights were built at; meaningful only when they are FP4. | |
| Serialization::WeightsMetadata | source_metadata_ |
| The loaded weights file's metadata, carried so save can write it back verbatim. | |
| WeightQuantization | weight_quantization_ { WeightQuantization::None } |
| What the live weights are, not what the source file was. | |
| Protected Attributes inherited from Mila::Dnn::Model< TDeviceType, TPrecision > | |
| std::unique_ptr< NetworkType > | network_ |
| The owned Network instance. | |
Constructor & Destructor Documentation
◆ LanguageModel()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineexplicitprotected |
- Parameters
-
network The transformer stack this model owns. runtime_mode Inference or Training, fixed for the model's lifetime. source_metadata The loaded weights file's metadata, written back verbatim by save so the result loads by the same path. weight_quantization What the live weights actually are, which is a load-time policy rather than a property of the source file. fp4_group_size The FP4 group those weights were built at.
All default, because a model reconstructed from a checkpoint has no weights metadata to carry; save refuses rather than writing a file that declares nothing.
Member Function Documentation
◆ awaitSampledToken()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineprotected |
Block until the last enqueueSampleNext()'s token id is host-visible.
Waits only for that sampling step – device work enqueued after it (the ahead-decoded forward) keeps running, which is what hides the per-token host gap.
◆ enqueueSampleNext()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineprotected |
Enqueue a sampling step without waiting for the host readback.
Decode-ahead half of the split sampleNext(): the token is written into token_out on the device (ready for the next decode step) and its id travels to the host asynchronously. awaitSampledToken() completes the pair. At most one enqueue may be outstanding.
◆ eosToken()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
protectedpure virtualnoexcept |
Implemented in Mila::Dnn::GptModel< TDeviceType, TPrecision >.
◆ finalLogitSoftcap()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineprotectedvirtualnoexcept |
Optional final-logit softcap the sampler applies (0 disables).
Gemma overrides this with its 30.0 cap; other models leave it at 0.
◆ generate()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlinenodiscard |
Generate tokens from a prompt, streaming each through on_token.
Blocking, serial token generation: the model owns the decode loop (it owns the KV cache and the device stream) and pushes every generated token (EOS excluded) to on_token on the caller's thread until it stops. Returns why it stopped – the one outcome the caller cannot reconstruct from the token stream. Timing/throughput are the harness's to measure from the callback cadence; the model keeps no stopwatch. Callers that want asynchrony own the threading (e.g. the Python ModelWorker runs this on its own thread).
- Parameters
-
prompt_tokens Input token ids. on_token Per-token callback invoked on the caller's thread. params Per-call generation parameters (loop bound + sampling). stop Stop token for cooperative cancellation.
- Returns
- Why generation stopped.
◆ maxSequenceLength()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
protectedpure virtualnoexcept |
◆ observe()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inline |
Watch activations flowing through matching components on matching passes.
The consumer's door onto observation. Every component already publishes on every inference pass, but publication is gated per component and the network is behind a protected accessor, so without this a caller cannot reach in – which is how the first consumer ended up with a purpose-built accessor bolted onto this class instead of using the machinery that was already there.
pattern is a component path with * matching any run of characters. What the paths are is answerable: see componentPaths().
model->observe( "*.lm_head", ComputePassMask::inference(),
[]( std::string_view path, ComputePass pass, std::string_view stage,
const ITensor& value )
{
// BORROWED and stream-ordered -- copy it here or synchronize yourself.
} );
ComputePass
The compute entry point that produced an observed value.
Definition Observation.ixx:29
Abstract interface providing essential tensor information and data access.
Definition ITensor.ixx:40
The tensor handed to the sink is borrowed for the duration of the call and ordered on the publishing component's stream, not valid on the host. Publication never synchronizes, because synchronizing is the clearest way for a probe to change what it is observing.
- Returns
- How many components matched. Check it – zero means nothing will publish, and downstream that is indistinguishable from a clean run.
◆ onGenerating()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
protectedpure virtual |
Prefill + decode implementation hook.
Derived classes own the full autoregressive generation loop. on_token must be called for every generated token except EOS. stop.stop_requested() must be checked on each decode step and generation must abort early when signalled, returning the GenerateStatus that reflects why the loop stopped.
- Parameters
-
prompt_tokens Input token ids. on_token Per-token callback. params Per-call generation parameters (loop bound + sampling). stop Stop token for cooperative cancellation.
- Returns
- Why generation stopped.
Implemented in Mila::Dnn::GemmaModel< TDeviceType, TPrecision >, Mila::Dnn::GptModel< TDeviceType, TPrecision >, Mila::Dnn::LlamaModel< TDeviceType, TPrecision >, and Mila::Dnn::QwenModel< TDeviceType, TPrecision >.
◆ sampleNext()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inlineprotected |
Sample the next token from a logits row on the device.
Lazily constructs the model-owned TokenSampler on first use (the network is built and the execution context valid by the time generation runs), then samples from the final row of logits, writing the int32 token into token_out in place (ready for the next decode step) and returning the host value.
◆ save()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inline |
Write this model's live weights as a safetensors weights file.
The inverse of load: what this writes is what that reads. Weights go out as they currently sit on the device, so a model loaded under FP4 or FP8 produces PRE-QUANTIZED weights – packed storage plus its scale companions. That is the point of the operation: quantization is a load-time policy, so the quantized bytes exist nowhere until a model has been built with one.
The source weights file's metadata is written back verbatim, so the result loads by the same path that loaded the original and is readable by any safetensors reader without Mila.
Family-agnostic by construction: the tensor vocabulary comes from the network's own flat-save traversal, so a family is covered as soon as every composite that owns a parameter drives both halves of it. A composite that only recurses and silently drops its own tensors is the failure this cannot see – the export tool's source reconciliation is what catches that.
- Parameters
-
path Destination weights file; parent directories are created.
- Exceptions
-
std::runtime_error if the model carries no weights metadata (it was reconstructed from a checkpoint), or if the file cannot be written.
◆ seedSampler()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inline |
Seed the sampler's RNG for reproducible generation.
Reproducibility is a property of the RNG stream, not of a single call: seed once (before a run or a session), then the token stream is deterministic for a given prompt and model. Deliberately not a per-call GenerateParams field, so a caller cannot accidentally reset the stream on every call.
◆ vocabSize()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
protectedpure virtualnoexcept |
◆ weightQuantizationScheme()
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
inline |
The scheme name save records for these weights, e.g.
"per_group_fp4_64".
Member Data Documentation
◆ source_metadata_
template<DeviceType TDeviceType, TensorDataType TPrecision>
|
protected |
The loaded weights file's metadata, carried so save can write it back verbatim.
Empty for a model reconstructed from a checkpoint, which save refuses.
The documentation for this class was generated from the following file:
- Mila/Src/Dnn/Core/LanguageModel.ixx
