Loading...
Searching...
No Matches
Mila::Dnn::QwenAttentionBlock< TDeviceType, TPrecision, TWeightPlan, TKvPolicy > Class Template Referenceexport
One Qwen 3.8 full-attention decoder block. More...
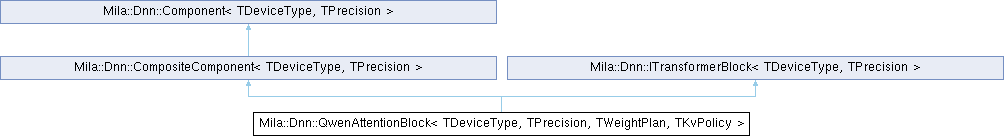
Inheritance diagram for Mila::Dnn::QwenAttentionBlock< TDeviceType, TPrecision, TWeightPlan, TKvPolicy >:
Classes | |
| struct | BlockBuildContexts |
| The per-child build contexts and split-scratch geometry this block implies. More... | |
Public Types | |
| using | AttentionType = GroupedQueryAttention<TDeviceType, TPrecision, TKvPolicy> |
| using | CompositeComponentBase = CompositeComponent<TDeviceType, TPrecision> |
| using | FeedForwardDownType = Linear<TDeviceType, TPrecision, typename PrecisionPlan::FeedForwardDown> |
| using | FeedForwardGateUpType = Linear<TDeviceType, TPrecision, typename PrecisionPlan::FeedForwardGateUp> |
| using | MR = typename DeviceTypeTraits<TDeviceType>::memory_resource |
| using | OutputGateType = AttentionOutputGate<TDeviceType, TPrecision, ActivationType::Sigmoid> |
| using | OutputProjectionType = Linear<TDeviceType, TPrecision, typename PrecisionPlan::OutputProjection> |
| using | PrecisionPlan = PrecisionPlanFor<TWeightPlan> |
| The resolved plan. Named so a caller can ask a block what it decided. | |
| using | QkvProjectionType = Linear<TDeviceType, TPrecision, typename PrecisionPlan::QkvProjection> |
| using | ResidualType = Residual<TDeviceType, TPrecision> |
| using | RmsNormType = RmsNorm<TDeviceType, TPrecision> |
| using | RopeType = Rope<TDeviceType, TPrecision> |
| using | SwigluType = Swiglu<TDeviceType, TPrecision, ActivationType::Silu> |
| using | TensorType = Tensor<TPrecision, MR> |
| Public Types inherited from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision > | |
| using | ComponentBase = Component<TDeviceType, TPrecision> |
| using | ComponentPtr = std::shared_ptr<Component<TDeviceType, TPrecision>> |
| Public Types inherited from Mila::Dnn::ITransformerBlock< TDeviceType, TPrecision > | |
| using | MR = typename DeviceTypeTraits<TDeviceType>::memory_resource |
| using | TensorType = Tensor<TPrecision, MR> |
Public Member Functions | |
| QwenAttentionBlock (const std::string &name, const QwenConfig &config, std::optional< DeviceId > device_id=std::nullopt) | |
| TensorType & | decode (const TensorType &input, dim_t position) override |
| Single-token decode at an absolute position (T == 1). | |
| MemoryStats | getMemoryStats () const override |
| Return the current memory allocation breakdown for this component. | |
| std::vector< ObservableStage > | getObservableStages () const override |
| Stages this component publishes, and the passes each is published on. | |
| MemoryStats | getRequiredMemory (const BuildContext &context) const override |
| What onBuilding() would allocate for this context, without allocating. | |
| const ComponentType | getType () const override |
| Get the component type identifier. | |
| dim_t | headDim () const noexcept |
| void | installSharedWorkspace (const QwenAttentionBlockWorkspace< TDeviceType, TPrecision > &workspace) |
| Install the transformer-owned shared activation workspace (pooling). | |
| dim_t | kvProjWidth () const noexcept |
| dim_t | numKVHeads () const noexcept |
| dim_t | packedQKVWidth () const noexcept |
| TensorType & | prefill (const TensorType &input, dim_t position_offset) override |
| Chunked prefill: process [B, T_chunk, model_dim] at an absolute offset. | |
| dim_t | qProjWidth () const noexcept |
| void | resetKvCache () override |
| Reset the KV cache (new generation session). | |
| bool | rewindKvCache (dim_t position) override |
| Rewind the KV cache fill position for prompt-prefix reuse. | |
| void | setState (const GqaState &state) override |
| Wire the shared GQA transient workspace (owned by the transformer). | |
| void | setUseFlashDecode (bool enabled) |
| Route this block's GQA op through the fused decode-attention kernel. BF16 only. | |
| void | setUseFlashPrefill (bool enabled) |
| Route this block's GQA op through the fused FlashAttention prefill kernel. | |
| bool | supportsKvCache () const noexcept override |
| True when the block's attention supports the KV-cache inference path. | |
| std::string | toString () const override |
| Generate a human-readable description. | |
| Public Member Functions inherited from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision > | |
| CompositeComponent (CompositeComponent &&) noexcept=default | |
| CompositeComponent (const CompositeComponent &)=delete | |
| CompositeComponent (const std::string &name) | |
| Construct composite component with name. | |
| CompositeComponent & | addComponent (ComponentPtr component) |
| Add a pre-constructed child component (chainable). | |
| size_t | childCount () const noexcept |
| Get the number of direct children. | |
| void | clearComponents () |
| Clear all child components. | |
| std::vector< std::string > | componentPaths () const |
| Every component path in this subtree, in traversal order. | |
| ComponentPtr | findComponent (const std::string &path) const |
| Resolve a dot-separated component path within this composite. | |
| ComponentPtr | getComponent (const std::string &name) const |
| Retrieve a direct child component by name. | |
| const std::vector< ComponentPtr > & | getComponents () const |
| Get all child components in insertion order. | |
| DeviceId | getDeviceId () const override |
| Get the compute device for this composite. | |
| std::vector< ITensor * > | getGradients () const override |
| Get all parameter gradients from all children. | |
| std::vector< ITensor * > | getParameters () const override |
| Get all parameters from all children. | |
| bool | hasChildren () const noexcept |
| Check if this composite has any children. | |
| bool | hasComponent (const std::string &name) const |
| Check if a named child component exists. | |
| size_t | observe (std::string_view pattern, Compute::ComputePassMask passes, Compute::ActivationObserver sink) |
| Attach sink to every component in this subtree whose path matches. | |
| CompositeComponent & | operator= (CompositeComponent &&) noexcept=default |
| CompositeComponent & | operator= (const CompositeComponent &)=delete |
| dim_t | parameterCount () const override |
| Count parameters across all children. | |
| bool | removeComponent (const std::string &name) |
| Remove a child component by name. | |
| void | saveFlatTensors (Serialization::SafeTensorsWriter &writer, const std::string &prefix, Serialization::TensorSavePass pass) const override |
| Recurse into children, extending the flat dotted prefix. | |
| void | stopObserving () |
| Detach every observer in this subtree and clear the shared sink. | |
| void | synchronize () override |
| Synchronize all child components. | |
| ComponentPtr | tryFindComponent (const std::string &path) const |
| Try to resolve a dot-separated component path within this composite. | |
| Public Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| Component (const std::string &name) | |
| Construct component with required name identifier. | |
| virtual void | build (const BuildContext &context) final |
| Build the component with the provided BuildContext (canonical overload). | |
| IExecutionContext * | getExecutionContext () const |
| Get the shared execution context. | |
| const std::string | getName () const |
| Get the component's name identifier. | |
| Compute::ComputePassMask | getObservedPasses () const noexcept |
| virtual std::vector< const ITensor * > | getOutputs () const |
| Return non-owning pointers to the tensors this component produces. | |
| virtual std::vector< std::string > | getParameterNames () const |
| List all available parameter names for this component. | |
| RuntimeMode | getRuntimeMode () const noexcept |
| TrainingMode | getTrainingMode () const noexcept |
| The current runtime behavioral mode of this Component. | |
| virtual bool | isBuilt () const final |
| Returns true if build() has completed successfully. | |
| bool | isInferenceMode () const noexcept |
| bool | isTrainingMode () const noexcept |
| virtual void | loadParameter (const std::string &, const Serialization::ITensorBlob &) |
| Load a parameter from serialized tensor data. | |
| void | setObservedPasses (Compute::ComputePassMask passes) noexcept |
| Select which passes this component publishes on. | |
| void | setTrainingMode (TrainingMode mode) |
| Set the runtime behavioral mode for this Component. | |
| virtual void | zeroGradients () |
| Clear all model-owned gradients for this component. | |
Protected Member Functions | |
| void | onBuilding (const BuildContext &context) override |
| Hook invoked by build() to allocate component buffers. | |
| void | onTrainingModeChanging (TrainingMode training_mode) override |
| Hook invoked when training mode is about to change. | |
| BlockBuildContexts | resolveBlockBuildContexts (const BuildContext &context) const |
| Protected Member Functions inherited from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision > | |
| template<typename TComponent> | |
| std::shared_ptr< TComponent > | getComponentAs (const std::string &name) const |
| Retrieve a typed child component by name. | |
| void | load_ (ModelArchive &archive, SerializationMode mode) override |
| Restore children from their nested scopes, mirroring save_(). | |
| void | onExecutionContextSet () override |
| Hook invoked after ExecutionContext is set. | |
| virtual void | optimize () |
| Virtual hook for graph optimization after construction. | |
| void | requireSerializableParameters () const override |
| No-op override: a composite names no parameters of its own. | |
| void | save_ (ModelArchive &archive, SerializationMode mode) const override |
| Protected Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| bool | hasExecutionContext () const noexcept |
| Check if execution context has been set. | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | loadParameterFromBlob (const std::string ¶m_name, const Serialization::ITensorBlob &blob, Tensor< TParameterPrecision, TMemoryResource > &target, const shape_t &expected_shape) |
| Load a tensor blob into a parameter tensor with validation. | |
| void | publish (Compute::ComputePass pass, std::string_view stage, const ITensor &value) const |
| Publish one activation to the observer, if this pass is being observed. | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | saveParameterToArchive (ModelArchive &archive, const std::string ¶meter_name, const Tensor< TParameterPrecision, TMemoryResource > ¶meter) const |
| Write one parameter tensor into the archive under "tensors/<name>". | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | saveParameterToWriter (Serialization::SafeTensorsWriter &writer, const std::string &flat_name, const Tensor< TParameterPrecision, TMemoryResource > ¶meter, Serialization::TensorSavePass pass) const |
| Drive one parameter through one pass of a flat safetensors save. | |
| void | setExecutionContext (IExecutionContext *context) |
| Set the execution context for this component. | |
Additional Inherited Members | |
| Static Public Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| static constexpr DeviceType | getDeviceType () |
| Compile-time device type for this component instance. | |
| static constexpr TensorDataType | getPrecision () noexcept |
| Compile-time tensor precision for this component instance. | |
| Protected Types inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| using | HostStagingMemoryResource = typename DeviceTypeTraits<TDeviceType>::host_staging_memory_resource |
| Host memory a device-resident parameter stages through. | |
| Protected Attributes inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| BuildContext | build_context_ { shape_t{ 1 }, RuntimeMode::Training } |
| The BuildContext stored at build time. | |
Detailed Description
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
requires PrecisionSupportedOnDevice<TPrecision, TDeviceType> && DecoderPrecisionPlan<PrecisionPlanFor<TWeightPlan>>
class Mila::Dnn::QwenAttentionBlock< TDeviceType, TPrecision, TWeightPlan, TKvPolicy >
requires PrecisionSupportedOnDevice<TPrecision, TDeviceType> && DecoderPrecisionPlan<PrecisionPlanFor<TWeightPlan>>
class Mila::Dnn::QwenAttentionBlock< TDeviceType, TPrecision, TWeightPlan, TKvPolicy >
One Qwen 3.8 full-attention decoder block.
- Template Parameters
-
TWeightPlan A precision plan (or a bare policy, which lifts to a uniform one). TKvPolicy KV-cache compression policy. These layers attend the FULL context, so a bounded ring is not applicable to them.
Member Function Documentation
◆ decode()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverridevirtual |
Single-token decode at an absolute position (T == 1).
- Returns
- Reference to the block-owned output [B, 1, model_dim].
Implements Mila::Dnn::ITransformerBlock< TDeviceType, TPrecision >.
◆ getMemoryStats()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverridevirtual |
Return the current memory allocation breakdown for this component.
Reflects allocations at the moment of the call. The returned stats naturally track the component lifecycle:
After construction – nothing; construction allocates none After build( Inference ) – parameters + T=1 state buffers After build( Training ) – parameters + T=full state buffers After setTrainingMode( Train ) – parameters + state + gradients
For CompositeComponent and Network, the returned stats are the recursive aggregate of all child components.
May be called at any time – no lifecycle preconditions.
- Returns
- MemoryStats reflecting current allocations.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getObservableStages()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverridevirtual |
Stages this component publishes, and the passes each is published on.
Lets a caller tell an uninstrumented component from a clean one before running anything. The pass qualifier is load-bearing rather than decorative: the stage set genuinely differs by pass, since a prefill can produce intermediates its decode never materializes.
- Returns
- Vector of stages; empty for components that publish nothing.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getRequiredMemory()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverridevirtual |
What onBuilding() would allocate for this context, without allocating.
Children are named rather than walked: each is built with its OWN context, and a generic recursion over getComponents() would size every one of them against the block's shape. See Specifications/MemoryFootprint.md section 4.4.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getType()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverridevirtual |
Get the component type identifier.
Used for serialization and runtime type identification.
- Returns
- Component type enum value.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ installSharedWorkspace()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inline |
Install the transformer-owned shared activation workspace (pooling).
Must be called before build(); onBuilding then routes each slot into the matching child via installSharedOutput and keeps the split scratch for the block's own views. Self-allocation remains the default for standalone blocks (tests).
◆ onBuilding()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverrideprotectedvirtual |
Hook invoked by build() to allocate component buffers.
Receives the stored BuildContext. Implementations must use config.allocationSeqLen() when sizing output buffers – this is the single call that makes Inference and Training allocate the correct buffer sizes automatically without per-component logic.
// Example -- Linear component:
shape_t out_shape =
{
config.batchSize(),
config.allocationSeqLen(), // 1 for Inference, T for Training
config_.getOutputFeatures()
};
output_ = std::make_unique<TensorType>( device, out_shape,
this->getName() + ".output" );
TensorShape shape_t
Row-major shape descriptor for tensor dimensional sizes.
Definition Tensor.Types.ixx:173
const std::string getName() const
Get the component's name identifier.
Definition Component.ixx:522
The default implementation forwards to the legacy onBuilding( const shape_t& ) overload for backwards compatibility. New components should override this overload directly.
- Note
- Do not call build() or onBuilding() from within this hook.
- Implementations should either succeed fully or leave no partial state, as a failed build() may be retried.
Takes the build-time configuration; use its allocationSeqLen() to obtain the correct output buffer sequence dimension.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ onTrainingModeChanging()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverrideprotectedvirtual |
Hook invoked when training mode is about to change.
Propagates the new mode to all child components. The hook runs with the Component's training mutex held; it MUST NOT call setTrainingMode().
- Parameters
-
training_mode New training mode (Normal or Eval)
Reimplemented from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision >.
◆ prefill()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverridevirtual |
Chunked prefill: process [B, T_chunk, model_dim] at an absolute offset.
- Returns
- Reference to the block-owned output [B, T_chunk, model_dim].
Implements Mila::Dnn::ITransformerBlock< TDeviceType, TPrecision >.
◆ resetKvCache()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverridevirtual |
Reset the KV cache (new generation session).
Implements Mila::Dnn::ITransformerBlock< TDeviceType, TPrecision >.
◆ rewindKvCache()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverridevirtual |
Rewind the KV cache fill position for prompt-prefix reuse.
Keeps the cache session live; positions [0, position) stay valid.
- Returns
- true when the layer's attention accepted the rewind (a bounded sliding-window ring refuses when the stale tail has overwritten the window a continuation would attend to).
Implements Mila::Dnn::ITransformerBlock< TDeviceType, TPrecision >.
◆ setState()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverridevirtual |
Wire the shared GQA transient workspace (owned by the transformer).
Called once after build, before any prefill/decode.
Implements Mila::Dnn::ITransformerBlock< TDeviceType, TPrecision >.
◆ setUseFlashPrefill()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inline |
Route this block's GQA op through the fused FlashAttention prefill kernel.
BF16 only. These layers are unbounded, so this is the unbounded kernel; the transformer couples the toggle to the shared score-buffer width.
◆ supportsKvCache()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverridevirtualnoexcept |
True when the block's attention supports the KV-cache inference path.
Implements Mila::Dnn::ITransformerBlock< TDeviceType, TPrecision >.
◆ toString()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvPolicy = NoKvCompression>
|
inlineoverridevirtual |
Generate a human-readable description.
- Returns
- String representation showing children
Reimplemented from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision >.
The documentation for this class was generated from the following file:
- Mila/Src/Dnn/Components/Transformers/Qwen/Qwen.AttentionBlock.ixx
