Loading...
Searching...
No Matches
Mila::Dnn::QwenTransformer< TDeviceType, TPrecision, TWeightPlan, TKvCachePolicy > Class Template Referenceexport
Qwen 3.8 transformer (decoder-only) for autoregressive inference. More...
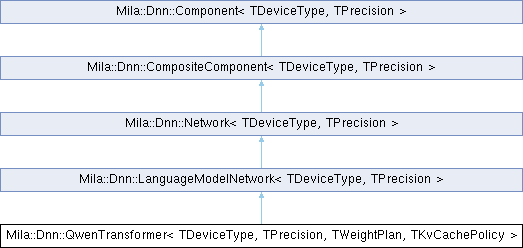
Inheritance diagram for Mila::Dnn::QwenTransformer< TDeviceType, TPrecision, TWeightPlan, TKvCachePolicy >:
Public Types | |
| using | AttentionBlockType = QwenAttentionBlock<TDeviceType, TPrecision, TWeightPlan, TKvCachePolicy> |
| using | ComponentPtr = typename NetworkBase::ComponentPtr |
| using | DeltaNetBlockType = QwenDeltaNetBlock<TDeviceType, TPrecision, TWeightPlan> |
| using | LmHeadLinearType = Linear<TDeviceType, TPrecision, typename PrecisionPlan::LanguageModelHead> |
| using | MR = typename DeviceTypeTraits<TDeviceType>::memory_resource |
| using | NetworkBase = LanguageModelNetwork<TDeviceType, TPrecision> |
| using | PrecisionPlan = PrecisionPlanFor<TWeightPlan> |
| using | RmsNormType = RmsNorm<TDeviceType, TPrecision> |
| using | TensorType = Tensor<TPrecision, MR> |
| using | TokenEmbeddingType |
| using | TokenIndexType = Tensor<dtype_t::INT32, MR> |
| using | TransformerBlockType = ITransformerBlock<TDeviceType, TPrecision> |
| Public Types inherited from Mila::Dnn::LanguageModelNetwork< TDeviceType, TPrecision > | |
| using | MR = typename DeviceTypeTraits<TDeviceType>::memory_resource |
| using | NetworkBase = Network<TDeviceType, TPrecision> |
| using | TensorType = Tensor<TPrecision, MR> |
| using | TokenIndexType = Tensor<TensorDataType::INT32, MR> |
| Public Types inherited from Mila::Dnn::Network< TDeviceType, TPrecision > | |
| using | ComponentPtr = typename CompositeBase::ComponentPtr |
| using | CompositeBase = CompositeComponent<TDeviceType, TPrecision> |
| using | MR = typename DeviceTypeTraits<TDeviceType>::memory_resource |
| Public Types inherited from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision > | |
| using | ComponentBase = Component<TDeviceType, TPrecision> |
| using | ComponentPtr = std::shared_ptr<Component<TDeviceType, TPrecision>> |
Public Member Functions | |
| QwenTransformer (const std::string &name, const QwenConfig &config, DeviceId device_id) | |
| TokenIndexType & | backward (const TokenIndexType &, const TensorType &) override |
| TensorType & | decode (const TokenIndexType &input, dim_t position) override |
| TensorType & | forward (const TokenIndexType &) override |
| MemoryStats | getMemoryStats () const override |
| Return the current memory allocation breakdown for this component. | |
| ModelType | getModelType () const |
| MemoryStats | getRequiredMemory (const BuildContext &context) const override |
| What build( context ) would allocate for the whole model, without allocating. | |
| void | loadParameters (WeightsReader &reader) |
| TensorType & | prefill (const TokenIndexType &input) override |
| PrefillChunking | prefillChunking (dim_t B, dim_t T_ctx) const |
| The prefill chunk this context length would use, and the largest the context permits. | |
| TensorType & | prefillFrom (const TokenIndexType &input, dim_t start_offset) override |
| Chunked prefill starting at an absolute position (prompt-prefix reuse). | |
| void | resetKvCache () |
| bool | rewindKvCache (dim_t position) override |
| Rewind every layer's cache to position. | |
| SequenceLogLikelihood | scoreTokens (const TokenIndexType &input) override |
| Teacher-forced log-likelihood of input – the corpus-perplexity path. | |
| std::string | toString () const override |
| Generate a human-readable description. | |
| Public Member Functions inherited from Mila::Dnn::LanguageModelNetwork< TDeviceType, TPrecision > | |
| LanguageModelNetwork (const std::string &name) | |
| virtual TokenIndexType & | backward (const TokenIndexType &input, const TensorType &output_grad)=0 |
| Full backward pass (training). | |
| virtual TensorType & | decode (const TokenIndexType &input, dim_t position)=0 |
| Inference decode – single-token autoregressive step. | |
| virtual TensorType & | forward (const TokenIndexType &input)=0 |
| Full-sequence forward pass – the training path, not the generation path. | |
| virtual TensorType & | prefill (const TokenIndexType &input)=0 |
| Inference prefill – process full prompt and populate the KV cache. | |
| virtual TensorType & | prefillFrom (const TokenIndexType &input, dim_t start_offset) |
| Chunked prefill starting at an absolute position (prompt-prefix reuse). | |
| virtual SequenceLogLikelihood | scoreTokens (const TokenIndexType &input) |
| Rewind the KV caches to position for prompt-prefix reuse (PromptCaching.md). | |
| Public Member Functions inherited from Mila::Dnn::Network< TDeviceType, TPrecision > | |
| Network (const std::string &name) | |
| Construct network (context managed by derived class). | |
| template<typename TOptimizer, typename TConfig> | |
| std::shared_ptr< TOptimizer > | createOptimizer (const TConfig &config) |
| Create and configure an optimizer for this network's parameters. | |
| DeviceId | getDeviceId () const noexcept override |
| Get the compute device for this composite. | |
| const ComponentType | getType () const override |
| Get the component type identifier. | |
| void | load (ModelArchive &archive, SerializationMode mode) |
| Restore this network's parameters from an archive. | |
| void | save (ModelArchive &archive, SerializationMode mode) const |
| Save network to archive. | |
| void | synchronize () override |
| Synchronize all child components. | |
| Public Member Functions inherited from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision > | |
| CompositeComponent (CompositeComponent &&) noexcept=default | |
| CompositeComponent (const CompositeComponent &)=delete | |
| CompositeComponent (const std::string &name) | |
| Construct composite component with name. | |
| CompositeComponent & | addComponent (ComponentPtr component) |
| Add a pre-constructed child component (chainable). | |
| size_t | childCount () const noexcept |
| Get the number of direct children. | |
| void | clearComponents () |
| Clear all child components. | |
| std::vector< std::string > | componentPaths () const |
| Every component path in this subtree, in traversal order. | |
| ComponentPtr | findComponent (const std::string &path) const |
| Resolve a dot-separated component path within this composite. | |
| ComponentPtr | getComponent (const std::string &name) const |
| Retrieve a direct child component by name. | |
| const std::vector< ComponentPtr > & | getComponents () const |
| Get all child components in insertion order. | |
| std::vector< ITensor * > | getGradients () const override |
| Get all parameter gradients from all children. | |
| std::vector< ITensor * > | getParameters () const override |
| Get all parameters from all children. | |
| bool | hasChildren () const noexcept |
| Check if this composite has any children. | |
| bool | hasComponent (const std::string &name) const |
| Check if a named child component exists. | |
| size_t | observe (std::string_view pattern, Compute::ComputePassMask passes, Compute::ActivationObserver sink) |
| Attach sink to every component in this subtree whose path matches. | |
| CompositeComponent & | operator= (CompositeComponent &&) noexcept=default |
| CompositeComponent & | operator= (const CompositeComponent &)=delete |
| dim_t | parameterCount () const override |
| Count parameters across all children. | |
| bool | removeComponent (const std::string &name) |
| Remove a child component by name. | |
| void | saveFlatTensors (Serialization::SafeTensorsWriter &writer, const std::string &prefix, Serialization::TensorSavePass pass) const override |
| Recurse into children, extending the flat dotted prefix. | |
| void | stopObserving () |
| Detach every observer in this subtree and clear the shared sink. | |
| ComponentPtr | tryFindComponent (const std::string &path) const |
| Try to resolve a dot-separated component path within this composite. | |
| Public Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| Component (const std::string &name) | |
| Construct component with required name identifier. | |
| virtual void | build (const BuildContext &context) final |
| Build the component with the provided BuildContext (canonical overload). | |
| IExecutionContext * | getExecutionContext () const |
| Get the shared execution context. | |
| const std::string | getName () const |
| Get the component's name identifier. | |
| virtual std::vector< ObservableStage > | getObservableStages () const |
| Stages this component publishes, and the passes each is published on. | |
| Compute::ComputePassMask | getObservedPasses () const noexcept |
| virtual std::vector< const ITensor * > | getOutputs () const |
| Return non-owning pointers to the tensors this component produces. | |
| virtual std::vector< std::string > | getParameterNames () const |
| List all available parameter names for this component. | |
| RuntimeMode | getRuntimeMode () const noexcept |
| TrainingMode | getTrainingMode () const noexcept |
| The current runtime behavioral mode of this Component. | |
| virtual bool | isBuilt () const final |
| Returns true if build() has completed successfully. | |
| bool | isInferenceMode () const noexcept |
| bool | isTrainingMode () const noexcept |
| virtual void | loadParameter (const std::string &, const Serialization::ITensorBlob &) |
| Load a parameter from serialized tensor data. | |
| void | setObservedPasses (Compute::ComputePassMask passes) noexcept |
| Select which passes this component publishes on. | |
| void | setTrainingMode (TrainingMode mode) |
| Set the runtime behavioral mode for this Component. | |
| virtual void | zeroGradients () |
| Clear all model-owned gradients for this component. | |
Static Public Attributes | |
| static constexpr EmbeddingTableResidency | kEmbeddingTableResidency |
Protected Member Functions | |
| void | onBuilding (const BuildContext &context) override |
| Hook invoked by build() to allocate component buffers. | |
| void | onTrainingModeChanging (TrainingMode training_mode) override |
| Hook invoked when training mode is about to change. | |
| void | save_ (ModelArchive &archive, SerializationMode) const override |
| Hook for concrete classes to save type-specific state. | |
| Protected Member Functions inherited from Mila::Dnn::Network< TDeviceType, TPrecision > | |
| virtual void | load_ (ModelArchive &archive, SerializationMode mode) override |
| Hook for concrete classes to validate type-specific state on load. | |
| void | verifyArchitectureCompatibility (const WeightsMetadata &metadata) |
| Verify that imported model is compatible with network architecture. | |
| Protected Member Functions inherited from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision > | |
| template<typename TComponent> | |
| std::shared_ptr< TComponent > | getComponentAs (const std::string &name) const |
| Retrieve a typed child component by name. | |
| void | onExecutionContextSet () override |
| Hook invoked after ExecutionContext is set. | |
| virtual void | optimize () |
| Virtual hook for graph optimization after construction. | |
| void | requireSerializableParameters () const override |
| No-op override: a composite names no parameters of its own. | |
| Protected Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| bool | hasExecutionContext () const noexcept |
| Check if execution context has been set. | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | loadParameterFromBlob (const std::string ¶m_name, const Serialization::ITensorBlob &blob, Tensor< TParameterPrecision, TMemoryResource > &target, const shape_t &expected_shape) |
| Load a tensor blob into a parameter tensor with validation. | |
| void | publish (Compute::ComputePass pass, std::string_view stage, const ITensor &value) const |
| Publish one activation to the observer, if this pass is being observed. | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | saveParameterToArchive (ModelArchive &archive, const std::string ¶meter_name, const Tensor< TParameterPrecision, TMemoryResource > ¶meter) const |
| Write one parameter tensor into the archive under "tensors/<name>". | |
| template<TensorDataType TParameterPrecision, typename TMemoryResource> | |
| void | saveParameterToWriter (Serialization::SafeTensorsWriter &writer, const std::string &flat_name, const Tensor< TParameterPrecision, TMemoryResource > ¶meter, Serialization::TensorSavePass pass) const |
| Drive one parameter through one pass of a flat safetensors save. | |
| void | setExecutionContext (IExecutionContext *context) |
| Set the execution context for this component. | |
Additional Inherited Members | |
| Static Public Member Functions inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| static constexpr DeviceType | getDeviceType () |
| Compile-time device type for this component instance. | |
| static constexpr TensorDataType | getPrecision () noexcept |
| Compile-time tensor precision for this component instance. | |
| Protected Types inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| using | HostStagingMemoryResource = typename DeviceTypeTraits<TDeviceType>::host_staging_memory_resource |
| Host memory a device-resident parameter stages through. | |
| Protected Attributes inherited from Mila::Dnn::Component< TDeviceType, TPrecision > | |
| BuildContext | build_context_ { shape_t{ 1 }, RuntimeMode::Training } |
| The BuildContext stored at build time. | |
Detailed Description
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
requires PrecisionSupportedOnDevice<TPrecision, TDeviceType> && EmbeddingPrecisionRole<PrecisionPlanFor<TWeightPlan>> && LanguageModelHeadRole<PrecisionPlanFor<TWeightPlan>>
class Mila::Dnn::QwenTransformer< TDeviceType, TPrecision, TWeightPlan, TKvCachePolicy >
requires PrecisionSupportedOnDevice<TPrecision, TDeviceType> && EmbeddingPrecisionRole<PrecisionPlanFor<TWeightPlan>> && LanguageModelHeadRole<PrecisionPlanFor<TWeightPlan>>
class Mila::Dnn::QwenTransformer< TDeviceType, TPrecision, TWeightPlan, TKvCachePolicy >
Qwen 3.8 transformer (decoder-only) for autoregressive inference.
Graph: TokenEmbedding -> [QwenAttentionBlock | QwenDeltaNetBlock] x N -> RmsNorm -> Linear (lm_head).
- Template Parameters
-
TWeightPlan A precision plan (or a bare policy, which lifts to a uniform one). The network requires the embedding and head roles on top of what its blocks require – no block instantiates a table.
Member Typedef Documentation
◆ TokenEmbeddingType
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
| using Mila::Dnn::QwenTransformer< TDeviceType, TPrecision, TWeightPlan, TKvCachePolicy >::TokenEmbeddingType |
Initial value:
TokenEmbedding<TDeviceType, dtype_t::INT32, TPrecision,
typename PrecisionPlan::EmbeddingTable, kEmbeddingTableResidency>
@ INT32
32-bit signed integer, host-compatible
Definition TensorDataType.ixx:49
Pure token embedding component (device-templated).
Definition TokenEmbedding.ixx:120
Member Function Documentation
◆ getMemoryStats()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
|
inlineoverridevirtual |
Return the current memory allocation breakdown for this component.
Reflects allocations at the moment of the call. The returned stats naturally track the component lifecycle:
After construction – nothing; construction allocates none After build( Inference ) – parameters + T=1 state buffers After build( Training ) – parameters + T=full state buffers After setTrainingMode( Train ) – parameters + state + gradients
For CompositeComponent and Network, the returned stats are the recursive aggregate of all child components.
May be called at any time – no lifecycle preconditions.
- Returns
- MemoryStats reflecting current allocations.
Implements Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ getRequiredMemory()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
|
inlineoverridevirtual |
What build( context ) would allocate for the whole model, without allocating.
At the chunk the rule picks against the device's free memory now, which is the chunk a build at this moment would take. See Specifications/MemoryFootprint.md section 11.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ onBuilding()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
|
inlineoverrideprotectedvirtual |
Hook invoked by build() to allocate component buffers.
Receives the stored BuildContext. Implementations must use config.allocationSeqLen() when sizing output buffers – this is the single call that makes Inference and Training allocate the correct buffer sizes automatically without per-component logic.
// Example -- Linear component:
shape_t out_shape =
{
config.batchSize(),
config.allocationSeqLen(), // 1 for Inference, T for Training
config_.getOutputFeatures()
};
output_ = std::make_unique<TensorType>( device, out_shape,
this->getName() + ".output" );
TensorShape shape_t
Row-major shape descriptor for tensor dimensional sizes.
Definition Tensor.Types.ixx:173
const std::string getName() const
Get the component's name identifier.
Definition Component.ixx:522
The default implementation forwards to the legacy onBuilding( const shape_t& ) overload for backwards compatibility. New components should override this overload directly.
- Note
- Do not call build() or onBuilding() from within this hook.
- Implementations should either succeed fully or leave no partial state, as a failed build() may be retried.
Takes the build-time configuration; use its allocationSeqLen() to obtain the correct output buffer sequence dimension.
Reimplemented from Mila::Dnn::Component< TDeviceType, TPrecision >.
◆ onTrainingModeChanging()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
|
inlineoverrideprotectedvirtual |
Hook invoked when training mode is about to change.
Propagates the new mode to all child components. The hook runs with the Component's training mutex held; it MUST NOT call setTrainingMode().
- Parameters
-
training_mode New training mode (Normal or Eval)
Reimplemented from Mila::Dnn::CompositeComponent< TDeviceType, TPrecision >.
◆ prefillChunking()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
|
inline |
The prefill chunk this context length would use, and the largest the context permits.
The largest rung whose whole predicted footprint fits the device's free memory, read now. Allocates nothing, so a caller may ask before the network is built; two calls made at different moments can disagree. See Specifications/MemoryFootprint.md section 11.
◆ prefillFrom()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
|
inlineoverride |
Chunked prefill starting at an absolute position (prompt-prefix reuse).
input is the FULL prompt tensor, so token index and absolute position coincide.
Prefix reuse will not survive Phase 3: a recurrent state cannot be rewound (section 7), so with 48 of 64 layers refusing, the all-or-nothing rewind always fails and every start_offset above 0 becomes unreachable through the model layer. The path stays because it is correct for the layers that do cache, and because snapshot and restore – which does work on a constant-size state – is Phase 6.
◆ rewindKvCache()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
|
inlineoverridevirtual |
Rewind every layer's cache to position.
All-or-nothing to the caller.
Reimplemented from Mila::Dnn::LanguageModelNetwork< TDeviceType, TPrecision >.
◆ save_()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
|
inlineoverrideprotectedvirtual |
Hook for concrete classes to save type-specific state.
REQUIRED override for concrete networks. Must write:
- Type identifier (e.g., "type": "MnistClassifier")
- Configuration parameters (batch_size, architecture constants)
- Shape metadata (for validation during Load())
This metadata enables the concrete class's Load() method to reconstruct the network.
Example implementation:
{
json meta;
meta["type"] = "MnistClassifier"; // Type identifier for runtime dispatch
meta["batch_size"] = batch_size_;
meta["input_shape"] = leading_shape_;
// ... other configuration
archive.writeJson("network/classifier_meta.json", meta);
}
void save_(ModelArchive &archive, SerializationMode) const override
Hook for concrete classes to save type-specific state.
Definition Qwen.ixx:737
ModelArchive provides high-level helpers for component serialization.
Definition ModelArchive.ixx:47
- Parameters
-
archive Archive to write to mode Serialization mode (passed from save())
Implements Mila::Dnn::Network< TDeviceType, TPrecision >.
◆ scoreTokens()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
|
inlineoverride |
Teacher-forced log-likelihood of input – the corpus-perplexity path.
Runs the same prefill the generation path runs, but evaluates the head at EVERY position instead of the final one, reading off the probability the model gave to the token that actually followed. A whole chunk of logit rows cannot be materialized at once (section 5), so the head is evaluated in windows of getLanguageModelHeadPositions() rows inside the chunk loop, and each window is reduced before the next overwrites it.
The reduction is on the HOST, in double. That is deliberate for a first implementation and is the slow part: every position moves a full logit row across PCIe and is reduced single-threaded, so this is minutes on a corpus rather than seconds. It is also the trustworthy version – a device kernel is an optimization that this can serve as the oracle for.
A width of 1 is valid and costs one head evaluation per token, which is decode's price. Widening trades memory for passes and changes no result.
◆ toString()
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
|
inlineoverridevirtual |
Generate a human-readable description.
- Returns
- String representation showing network name and children
Reimplemented from Mila::Dnn::Network< TDeviceType, TPrecision >.
Member Data Documentation
◆ kEmbeddingTableResidency
template<DeviceType TDeviceType, TensorDataType TPrecision, typename TWeightPlan = NoWeightQuant, KvCachePolicy TKvCachePolicy = NoKvCompression>
|
staticconstexpr |
Initial value:
=
( TDeviceType == DeviceType::Cuda )
? EmbeddingTableResidency::Host : EmbeddingTableResidency::Device
EmbeddingTableResidency
Where the embedding table's bytes live.
Definition TokenEmbedding.ixx:79
Abstract interface for compute device implementations.
Definition Device.ixx:41
The documentation for this class was generated from the following file:
- Mila/Src/Dnn/Components/Transformers/Qwen/Qwen.ixx
